Do crop descriptors really rule the world?

Helen Anne Curry and Sabina Leonelli’s chapter in Agricultural Science as International Development: Historical Perspectives on the CGIAR Era, entitled “Crop Descriptors and the Forging of ‘System-Wide’ Research in CGIAR,” advances a provocative argument: IBPGR’s famous, even iconic, standardized descriptor lists — the shared controlled vocabularies used to record traits like plant height, fruit shape and disease resistance in many genebanks around the world — were never just a neutral book-keeping exercise. By 1997, the authors note, something like 80% of genebank curators were using them. Those that didn’t risked being marginalized and excluded from other activities.

The implication is that what seemed like rather “boring” infrastructure quietly decided which traits got noticed, valued and studied, and thus whose priorities counted in the process of conservation and use of plant genetic resources. But not just conservation and use of plant genetic resources. No, descriptors in effect helped drive CGIAR’s whole research agenda for 30 years:

We argue that the project of producing descriptors both defined and embodied CGIAR institutional identity and objectives as these evolved from the 1970s to the 2000s.

I have some sympathy with some of this, not gonna lie. Standards are never innocent or neutral, and it’s a useful corrective to point out that coding conventions, qualitative state labels and data formats can carry as much institutional power as more seemingly consequential, not to say exciting, technical interventions.

But I think the authors overstate their case. Here’s why.

Continue reading “Do crop descriptors really rule the world?”
Data is not the destination

Mike Jackson’s account of the early molecular work at IRRI’s International Rice Genebank is a nice reminder that the idea of the “genomic genebank” (as he calls it) is not as new as it may sounds. In the 1990s, RAPD and AFLP markers were already being used to identify duplicates, reveal genetic structure and, more ambitiously, to predict which accessions might possess useful traits. It’s the continuation of the trajectory I traced in my recent post on descriptors: from names and human-scored traits to photographs, digital phenotypes, molecular markers and now genomic information, each adding a layer of information that makes the collection more searchable and usable. The question keeps shifting from “what do we have?” to “which of what we have might be useful?”

Jackson’s story is also a key piece of the argument I tried to make in another recent post: preserving options is only the beginning. More, and better, information makes options easier to discover, but discovering an option is not the same as exercising it. The harder question is what happens next: how do we turn knowledge about what’s in a collection into actual selection, testing, breeding, adoption and impact? Data can open the door to better use of genebank collections. It cannot walk through it for us.

And there is a danger here. As our information about genebank collections becomes ever more layered, richer and more precise, it can start to look as though we’re solving the problem of use. We are not. We are solving the problem of finding possibilities. That’s only one part of the journey. A genomic prediction is not a breeding line; a photograph is not a phenotype under farmers’ conditions. The distance between knowing an option exists and actually exercising it still has to be travelled. That is a social and institutional process as much as a biological and technological one, and it starts only when the search is over.

Brainfood: The diverse lives and times of crop diversity

The plants that statistics forgot

FAO has just put out new guidance on capturing wild foods and neglected and underutilized species (NUS) in dietary surveys. It’s very much worth a look, even if your interest runs more to grain landraces on the farm than to greens gathered from the forest. The methodology is built to overcome a very real problem: standard dietary assessment tools are generally designed with the main staples in mind, so anything outside that narrow frame (think foraged, seasonal, localized, thinly documented) tends to fall straight through the cracks.

FAO’s fix is a set of very sensible, practical steps: engage local knowledge holders to compile inventories under their own names for things, survey markets to see what’s actually being sold and eaten, map harvest calendars against agroecological zones and seasons, and build simple identification tools (photobooks, reference databases) that let enumerators and communities work from a shared understanding of what they’re counting.

None of that machinery is specific to wild foods though. The same toolkit could easily be adapted to survey the diversity hiding in plain sight on farms: crops and landraces known only by a few, grown in a handful of villages, marginalized, on their way to be forgotten. And invisible to national crop statistics that only track the main crops and the most common named improved varieties, if that. A market survey designed to catch wild greens sold at the roadside works just as well for catching a local bean landrace in the same market. A harvest calendar built to track when forest foods peak works just as well for tracking when fonio gets planted or harvested, and why farmers still bother with it. Great for quantifying the opportunity presented by “opportunity crops.”

And there’s a useful downstream application: surveys built this way could help flag where crop diversity is thinning out on the ground, or where it’s abundant but under-represented in genebank holdings. In other words, the kind of gap analysis that ought to be steering germplasm collecting missions.

FAO’s framing kind of gestures at this already: wild, managed and cultivated aren’t three separate boxes but points on a continuum. A methodology built to navigate that blurriness for wild foods is also a methodology that ought to work for navigating the blurriness at the cultivated end. It would be a shame if this toolkit stayed confined to the wild-food side of the spectrum when the conceptual heavy lifting behind it applies just as well to neglected cultivated diversity.

Putting names and faces to organic seed diversity

LIVESEEDING is a project…

…to foster the growth of the organic sector and transition towards more sustainable local food systems by delivering high quality organic seed of diverse cultivars adjusted to organic farming for a wide range of crops.

It is funded by Horizon Europe (Innovation Action), the Swiss State Secretariat for Education, Research and Innovation and UK Research and Innovation, and gathers 37 partners from 16 countries.

The project is producing some interesting resources, but the ones I like best are actually a little difficult to find on their website. So difficult, in fact, that I have to resort to linking to them via a search result on Organic Farm Knowledge.

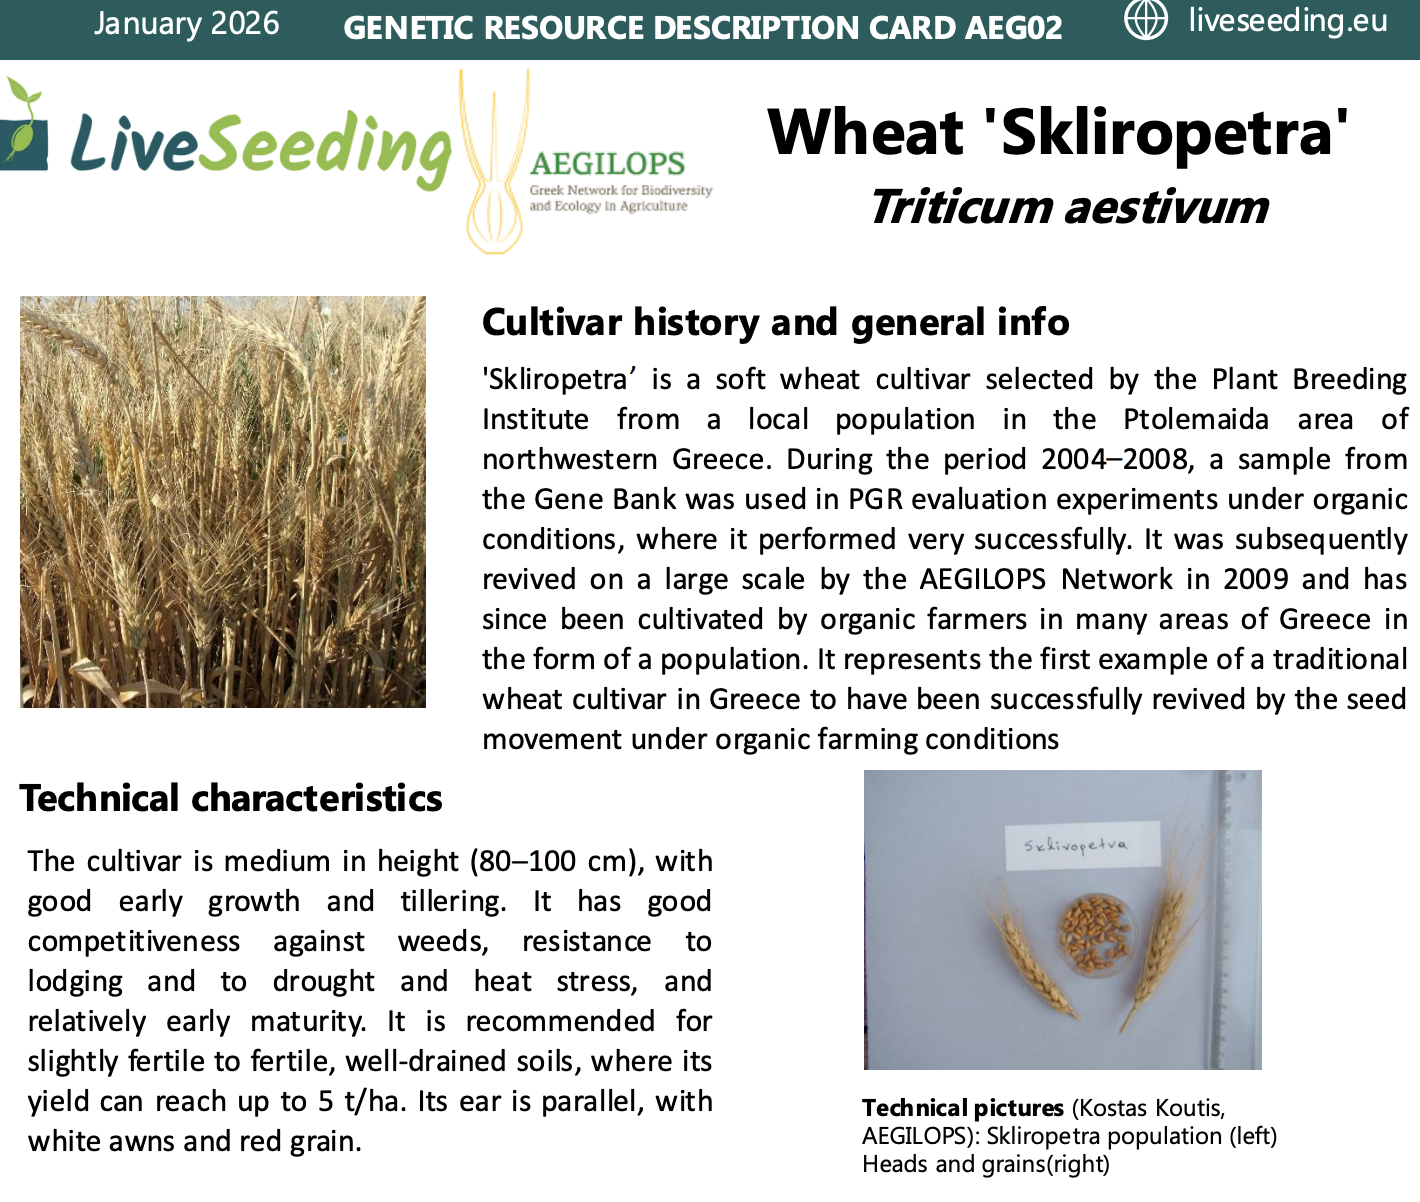
They are plant genetic cards, each providing information on a specific cultivar, “supporting its identification, conservation, cultivation and use by farmers, seed practitioners, breeders, researchers and other stakeholders of the seed system.”

Here’s a little piece of one such card from Greece.

There’s also something called the EU Organic Seed Database “to create more transparency for the EU member states and for plant reproductive material suppliers regarding available offers of organic plant reproductive materials and to increase the supply of organic plant reproductive material in the EU member states and Switzerland.”

To be honest, I haven’t really played around with it enough to form a definitive judgement, but it does seem a little complicated to navigate at first blush. If anyone has a go, and has an opinion, please let me know in the comments. However, the plant genetic cards do have links to possible sources of seeds.